Suppose a software company is taking on more work. Developers can build features faster, but every release still waits for the one person who remembers the commands. When a database fails, the team knows backups exist but cannot say how long recovery takes. Meanwhile, several projects share one cloud bill, leaving nobody sure what each service costs.
Adding servers might help compute capacity. It leaves other questions open: who owns this service, can the team reproduce a release, what data can be recovered, and how much cash and staff time does it consume? This is a fictional situation, not a report about a particular company.
I see a company's technology foundation as the ability to assign ownership, change systems, check results, and respond to failure at a cost people understand. Cloud and infrastructure belong in that foundation, alongside delivery practices and financial decisions.
The AWS Well-Architected Framework and Google Cloud Well-Architected Framework provide useful questions about operations, security, reliability, performance, and cost. I would use them to examine decisions, rather than as reasons for every business to buy the same services or adopt the same architecture.
Start with the business work a system supports
Before choosing tools, I would want an inventory of the systems actually in use: the website, ERP, customer services, integrations, repositories, and the systems used to release software. Each entry should identify its users, purpose, data, dependencies, owner, and the people affected when it stops.
The surrounding dependencies are easy to overlook: domains, DNS, certificates, provider accounts, and access to backups. An application cannot return to service if its domain has expired. A restored database does not help if the team cannot access the replacement environment.
Business owners and technical owners should agree on impact. An ordering service and a developer sandbox do not necessarily need the same budget or recovery strategy. That distinction helps the team choose where to begin and lets management see which business work a proposed investment protects.
Connect the foundation to business work
- Work and ownership
Which work does the system support, who uses it, who owns it, and who is affected by interruption?
- Agreed constraints
Data, access, recovery objectives, operating capacity, and budget
- Cloud and infrastructure
Choose services, networking, data storage, and operations around those constraints
- Release and recovery path
Identify versions, reproduce releases, test boundaries, and rehearse response
- User outcomes and cost
Review successful work, recovery time, payments, and staff hours
Use findings to revisit constraints and investment priorities
Choose cloud around the work and the team
Workload placement should reflect data needs, connectivity, demand, acceptable interruption, and the people available to operate it. A managed database service may remove some routine work, in exchange for fees, constraints, and data-exit arrangements that need examination. A more self-managed environment offers control but also needs people who can patch, protect, and recover it.
Kubernetes can be useful when there is enough orchestration work and a team able to operate it. A tool's name is not evidence that it fits a company of a particular size. A simple workload may start with a managed application service or a smaller arrangement. Microservices and multiple clouds also need a reason grounded in the work, rather than complexity added to look ready for growth.
I would ask who can respond when the primary operator is away, whether the environment can be rebuilt from documented configuration, and what makes leaving a service difficult. Those operating obligations belong in the decision alongside the price of a machine.
Establish access, backup, and recovery early
Separate people's accounts, application identities, and release credentials. Give each the access its work needs, use suitable authentication, and store secrets such as passwords and keys where access can be controlled. Keep them out of source code and define how access is removed when people or responsibilities change.
Moving to cloud does not move every responsibility to the provider. AWS's shared responsibility model explains that customer responsibilities vary with the services selected. Check who handles operating systems, configuration, data, permissions, and backups for each service. A provider-managed component still needs configuration and use appropriate to the workload.
High availability, backup, and disaster recovery address different failure conditions. Redundant machines may help when one machine fails. They do not automatically recover deleted data if a bad command is replicated across every copy.
For one important service, suppose the business chooses a recovery time objective (RTO) of four hours and a recovery point objective (RPO) of one hour. RTO describes the target time to restore the required service after interruption; RPO describes the acceptable data-loss window. These are hypothetical objectives chosen for an example, not standards for every company or evidence that an environment already meets them.
AWS recommends defining recovery objectives for each workload and its dependencies. Restoring the required service involves more than starting a database: the application, access, network, and important user workflow must work too. The recovery strategy should match the required time, acceptable data loss, cost, and complexity.
A backup file does not establish that recovery will meet the objective. Rehearse restoration in an isolated environment, check data completeness and the actual workflow, measure from the agreed service-interruption boundary through detection, decision, restoration, and validation, and record unresolved gaps. Protect backups from unauthorized access and deletion as well.
Make releases reproducible
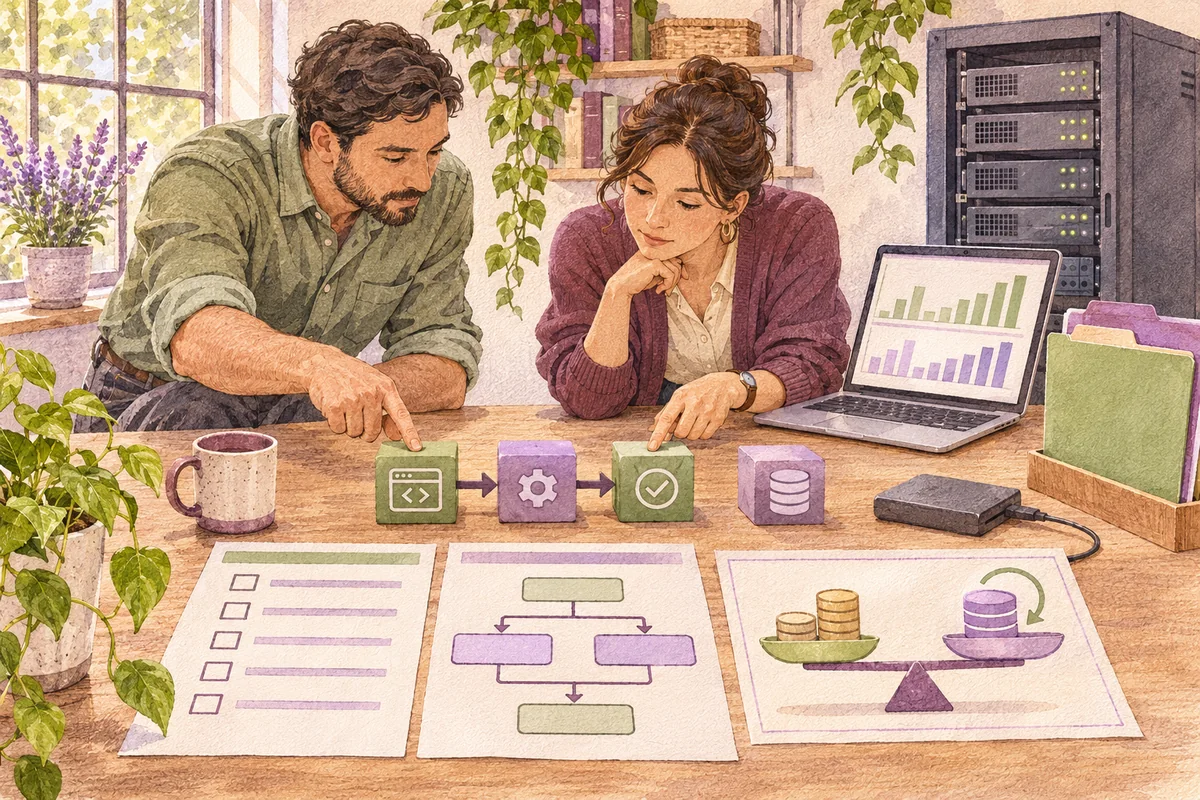
If only one person knows the command sequence, the risk extends beyond their next holiday. Every manual attempt can differ from the previous one. An early goal should be to explain and reproduce a particular release, without beginning with a complicated automation platform.
Version application code, release scripts, infrastructure defined as code, and appropriate configuration without committing secrets. Build a package once, test that version, and promote the same package through test and production. Keep environment-specific settings separate. DORA's deployment automation guidance describes reproducible deployment and knowing which build is running in each environment.
Automated checks should provide prompt, dependable feedback. Start with trusted runners the team can operate, separate test permissions from production-release permissions, and extend the process according to risk. A passing pipeline does not prove every business rule correct. Authorization, integration, and damaging failure cases still need relevant tests.
Continuous delivery means keeping software ready to release. It differs from continuous deployment, which automatically releases changes to production. A team can prepare a releasable version and retain an authorized decision about timing. DORA distinguishes those practices. More frequent deployment is not a useful goal by itself if the underlying process remains fragile.
From one change to its observed result
- A traceable change
Record its reason, code version, configuration, and data effects without committing secrets
- Build and check one package
Run relevant checks and retain the package version and results
- Test in staging
Use the same package to test authorization, interfaces, and the database-change plan
- Choose release timing by risk
An authorized owner reviews evidence, timing, and stop conditions. Every change need not release automatically
- Release and observe user work
Check the service and important workflows. Limit impact and respond when the agreed stop conditions are met
Feed evidence and incidents back into the change
Rolling back an application does not automatically reverse data or external transactions. If a new version changes a schema or deletes information, old code may no longer work with the changed data. Plan compatible transitions where appropriate, or rehearse a recovery or fix-forward approach. Restoring old data may overwrite newer transactions, so the responsible people need to decide from business consequences rather than the presence of a rollback button.
Observe the user's work, not just the machines
CPU and memory help explain technical problems. A healthy machine can still leave a user unable to save an order. I would want signals from important workflows: whether a transaction succeeded, how long it took, where work is stuck, and whether data reached its destination.
Define service-level objectives (SLOs) with the measurement method, window, and included events. Then connect metrics, logs, and traces to the questions they help answer. An alert needs an owner and an action. If every small change has the same urgency, operators cannot tell which event needs attention first.
Observability data also creates cost and risk. Set retention, redact sensitive information, restrict access, and choose detail according to its value. Keeping everything forever does not guarantee a better investigation. Findings and prevention work should return to the team's plan.
Count both payments and staff time
The FinOps Foundation framework connects technology value with collaboration and accountability. I would start by identifying which business service incurs a cost, who owns its budget, and who acts when spending changes. Separate accounts or use tags and labels for projects, environments, and owners, with an agreed way to allocate shared costs. FinOps Allocation offers guidance without prescribing one organizational structure.
Inspect idle machines, abandoned storage, always-on test environments, resource sizing, data egress, log costs, and commitments. A budget alert does not stop spending unless an actual policy or control enforces that limit. Downsizing should not break service objectives. Long-term commitments should follow an understood demand pattern rather than precede it because a discount is available.
The following model is entirely hypothetical. It compares one service under the assumption that both options can meet equivalent workload, security, and recovery requirements. Those capabilities still need verification before selection. These are not provider prices or measured outcomes. The THB 800 hourly value is an internal assumption for evaluating staff resources, not a market wage rate.
| Monthly item | More self-managed | More managed services |
|---|---|---|
| Cloud and services within the same defined scope | THB 60,000 | THB 80,000 |
| Routine operating hours | 60 hours | 25 hours |
| Allocated staff value at THB 800 per hour | THB 48,000 | THB 20,000 |
| Service payments plus estimated staff-resource value | THB 108,000 | THB 100,000 |
The second option increases service payments by THB 20,000 a month while releasing thirty-five hours, valued at THB 28,000 in this model. The combined difference is THB 8,000 a month. This is a scoped resource-cost comparison, not THB 8,000 of cash savings: payroll may remain unchanged, and released hours do not automatically produce revenue. Do not add allocated time again if the same payroll cost is already included.
The model assumes the first option continues the existing setup without an additional one-time cost. The second includes a separate THB 120,000 estimate for migration and setup, including transition work distinct from routine operating hours. Under those assumptions, the first option totals THB 1,296,000 over twelve months. The second totals THB 1,320,000 including setup, or THB 24,000 more in that period. The model does not value outage losses or other unspecified costs, so it is not an exhaustive total-cost assessment. These totals are not cash-flow forecasts or a payback calculation. Actual incremental payments, benefits, and timing need separate evaluation.
Before deciding, I would ask what the thirty-five released hours will be used for, whether that use is feasible, and what evidence supports the required recovery capability. A lower invoice may require more staff time. A higher-priced service still needs to justify its place.
Unit costs help connect spending to business work, such as cost per customer served, successful transaction, or AI workflow meeting its acceptance criteria, with consistent scope, denominator, and measurement period. FinOps Unit Economics emphasizes relating spending to value. A cheaper request is not enough if failures or user waiting time rise.
Give improvement work owners and evidence
I would use ninety days as an initial planning horizon, not a promise that every company can complete its foundation work in that time. Begin with systems, access, and cost inventories. Identify gaps that could stop work or prevent recovery, then choose one important service as a pilot.
Next, establish a reproducible release path, rehearse recovery, and make costs attributable to owners. Use the later period to compare results with the baseline, fix unresolved gaps, and extend only the patterns the team can operate. Moving everything at once merely to show progress introduces its own risk.
| Work selected | Accountable lead | Evidence to review |
|---|---|---|
| Understand critical systems and dependencies | Business and technical owners | An agreed inventory, ownership, and business-impact assessment |
| Limit access and protect secrets | Identity owner and team lead | Role-appropriate access, revocation procedure, and agreed checks |
| Release and recover according to plan | Service and release owners | Traceable versions and configuration, recovery-exercise results, and unresolved gaps |
| Attribute costs and address anomalies | Service owner with finance | Allocated spending, shared-cost rules, and an alert owner |
Measure change lead time, failed changes after release, recovery time in rehearsals, user-workflow quality, operating hours, and unit costs using consistent boundaries. Avoid collecting so much data that the team cannot act on findings. Owning a complete list of tools should not earn a passing score.
The first task I would choose is one service with a clear business consequence. Ask another team member to explain its path from incoming data through release and recovery. If the team cannot explain who does what, which version is used, or how much money and time it takes, that gap is a concrete piece of foundation work to do next.
Sources and scope
This article uses official guidance from AWS, Google Cloud, DORA, and the FinOps Foundation. It is not an architecture assessment of a particular company. The diagrams are newly created. Costs, recovery objectives, and the ninety-day plan are illustrative assumptions or the author's proposal, to be adapted to the actual systems, team, and customer commitments.